AI Leaderboard
When AI Predicts a Draw, It Is Right 1 Time in 4
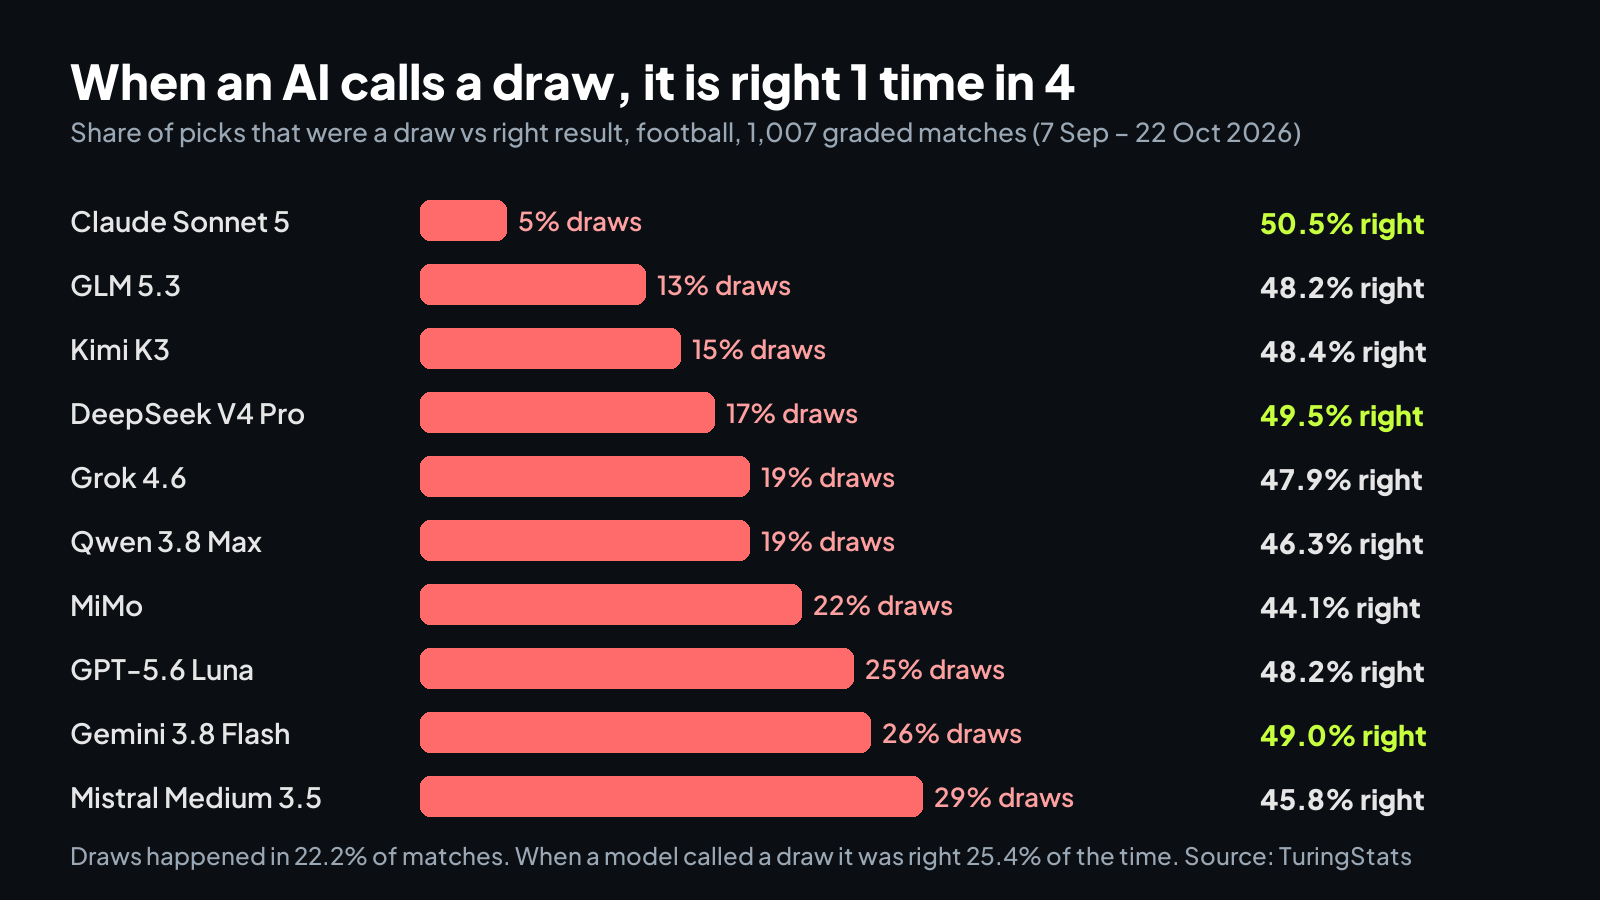
10 AI models, 1,007 graded football matches: draw calls were right 25.4% of the time. The models that call fewer draws do better.
Ask an AI chatbot who wins a football match and, now and then, it will tell you: a draw. It sounds careful. Our data says it is the single most common way AI models get football wrong.
Before every match, TuringStats asks the same 10 AI models to pick the result and the score, then grades every pick after the final whistle. From 7 September to 22 October 2026 that came to 1,007 graded football matches across the Premier League, Champions League, La Liga, Serie A, Bundesliga, Ligue 1 and more.
1. Draws happen often. Predicting them almost never works.
- 22.2% of the matches ended in a draw.
- The models called a draw 1,899 times. They were right 25.4% of the time.
- Had those same picks gone to the side most models favoured instead, they would have been right 42.4% of the time.
A draw is common, but in any single match it is rarely the most likely result. Calling one is usually a hedge, and hedges lose.
2. The models that call fewer draws do better
| Model | Draw picks | Right result |
|---|---|---|
| Claude Sonnet 5 | 5% | 50.5% |
| DeepSeek V4 Pro | 17% | 49.5% |
| Gemini 3.8 Flash | 26% | 49.0% |
| Kimi K3 | 15% | 48.4% |
| GLM 5.3 | 13% | 48.2% |
| GPT-5.6 Luna | 25% | 48.2% |
| Grok 4.6 | 19% | 47.9% |
| Qwen 3.8 Max | 19% | 46.3% |
| Mistral Medium 3.5 | 29% | 45.8% |
| MiMo | 22% | 44.1% |
Claude, the most accurate model, calls a draw in only 5% of matches. Mistral and MiMo call the most draws and sit at the bottom. It is not a perfect rule (Gemini calls plenty of draws and still does well), but the pattern is clear.
3. What we changed
When most models agreed on a draw (138 matches), the draw came in only 24.6% of the time. Picking the leading side instead would have lifted the overall majority record from 49.4% to 51.8% on the same matches. That is measured on past data, so the real gain may be smaller.
From 22 October the consensus pick on TuringStats chooses between the two teams, and flags a likely draw separately when four or more models expect one. Every past pick stays exactly as it was published.
Method
Same 10 models, same match data for every match (form, venue, head-to-head and, where available, team news), never the betting odds. Only each model's latest pick before kick-off counts. Full numbers, by sport and by month: AI prediction accuracy report. Free to use with credit to TuringStats.