AI Leaderboard
We tracked 10 AI models on 1,935 real games. Here's which one predicts sports best.
Claude, Gemini, GPT, Grok, DeepSeek and five more, graded on 19,350 predictions. The top model won by a hair; the real signal is when all 10 agree.
Every week someone publishes a version of "we asked ChatGPT, Gemini and Grok who will win". Those pieces stop at the question. Nobody goes back to check who was right.
We did. Before every game, TuringStats asks the same 10 AI models to pick a winner and a score, and grades each pick after the final whistle. Over five weeks that came to 1,935 games and 19,350 graded predictions, across soccer, hockey, baseball, the NFL and six smaller sports. Every model saw the same games, the same data and the same prompt.
Here is what we found.
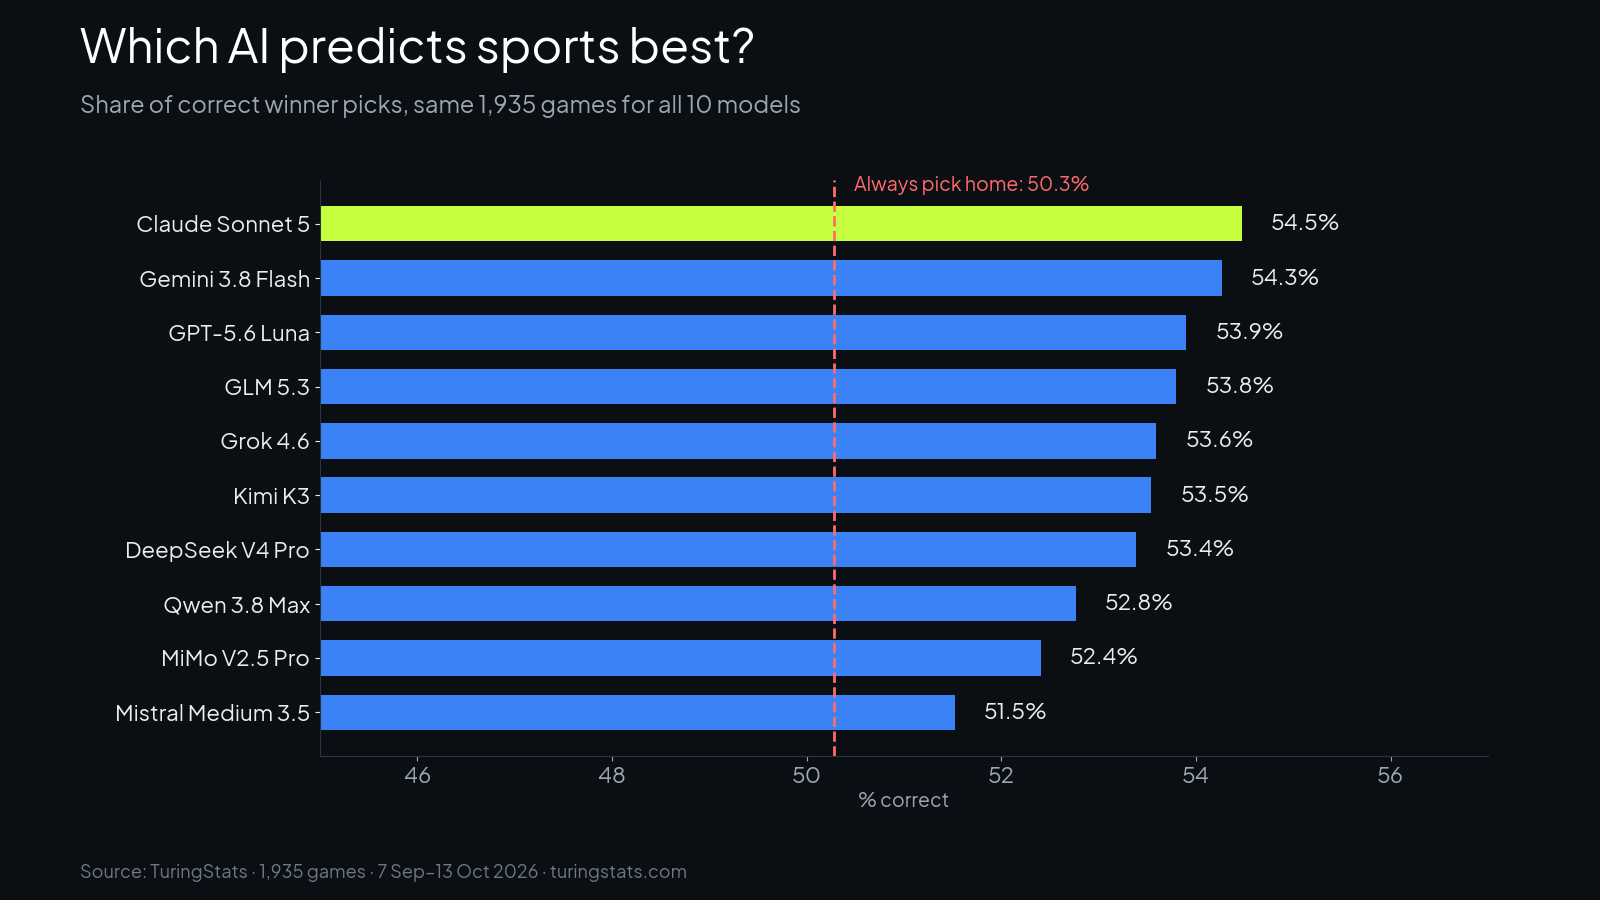
1. The winner is Claude, but only just
| Rank | Model | Correct winner picks |
|---|---|---|
| 1 | Claude Sonnet 5 | 54.5% |
| 2 | Gemini 3.8 Flash | 54.3% |
| 3 | GPT-5.6 Luna | 53.9% |
| 4 | GLM 5.3 | 53.8% |
| 5 | Grok 4.6 | 53.6% |
| 6 | Kimi K3 | 53.5% |
| 7 | DeepSeek V4 Pro | 53.4% |
| 8 | Qwen 3.8 Max | 52.8% |
| 9 | MiMo V2.5 Pro | 52.4% |
| 10 | Mistral Medium 3.5 | 51.5% |
The simplest possible strategy, "always pick the home team", scored 50.3%. All 10 models beat it, but not by much.
The gap from first to last is just three points. Over a sample this size, only the distance between the top and the bottom is clearly more than noise: on a bootstrap test, Claude's lead over Mistral sits between 0.8 and 5.2 points (95% interval). The order of the middle eight could flip next month.
Takeaway: if you are choosing a single chatbot for sports picks, the brand matters far less than the marketing suggests.
2. When an AI says it is confident, it usually means it
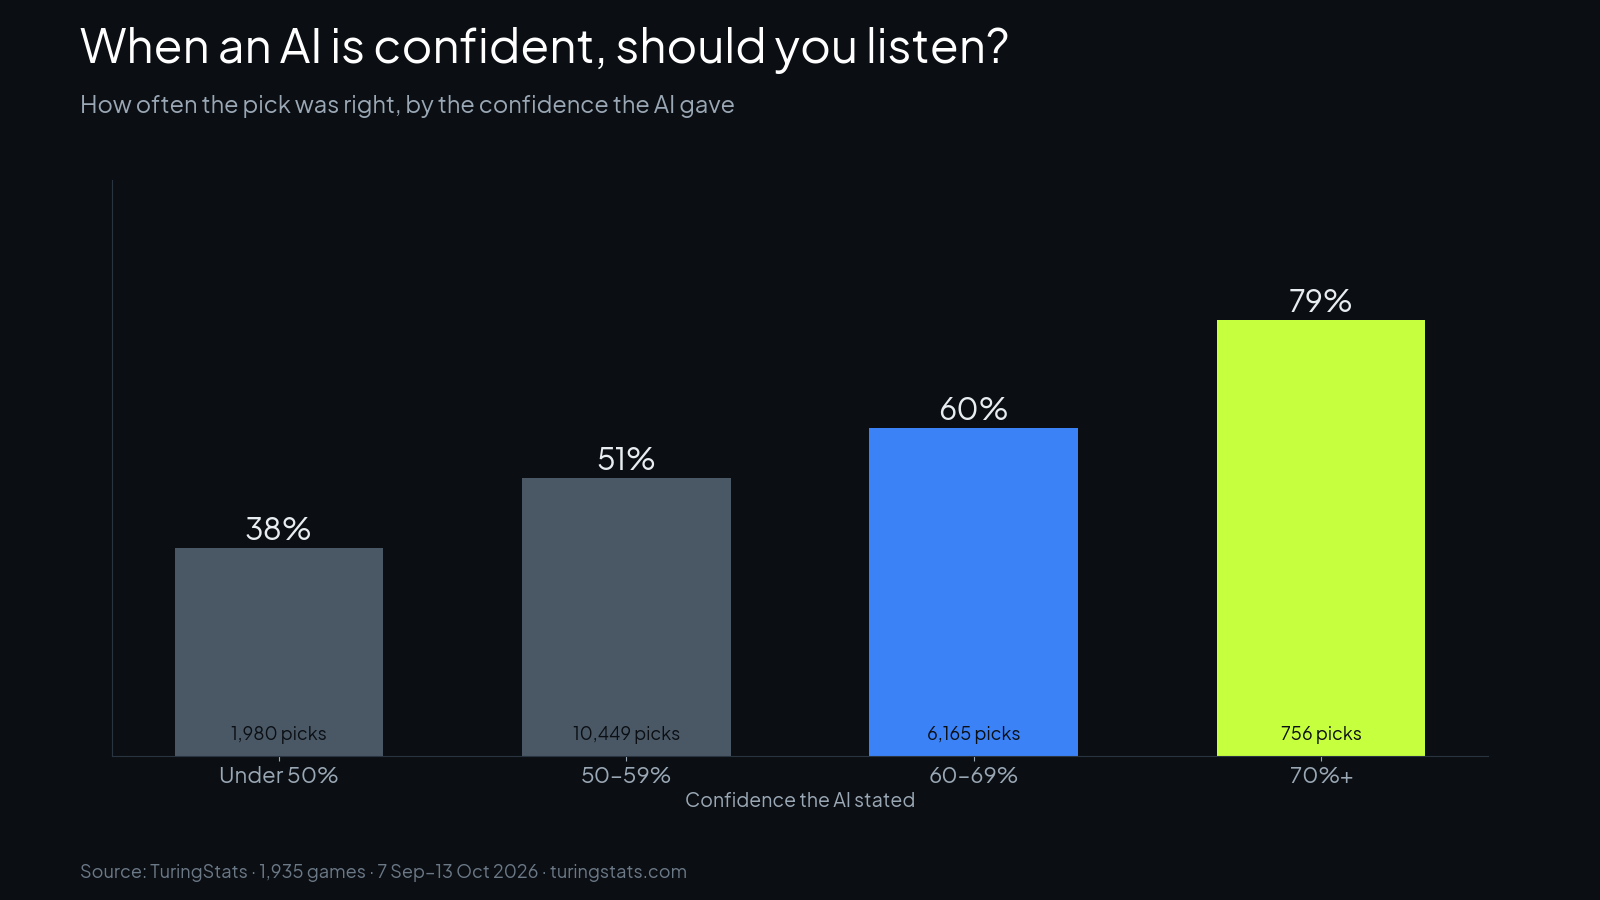
Each model also gives a confidence number with every pick. That number turned out to be the most useful thing in the dataset:
- Under 50% confidence: right 38% of the time
- 50–59%: 51%
- 60–69%: 60%
- 70% or more: 80% (756 picks)
The scale works almost exactly as you would hope. The catch is that high-confidence picks are rare (under 4% of all picks) and cluster on lopsided games, where the favourite was obvious anyway.
3. Every AI loves the home team
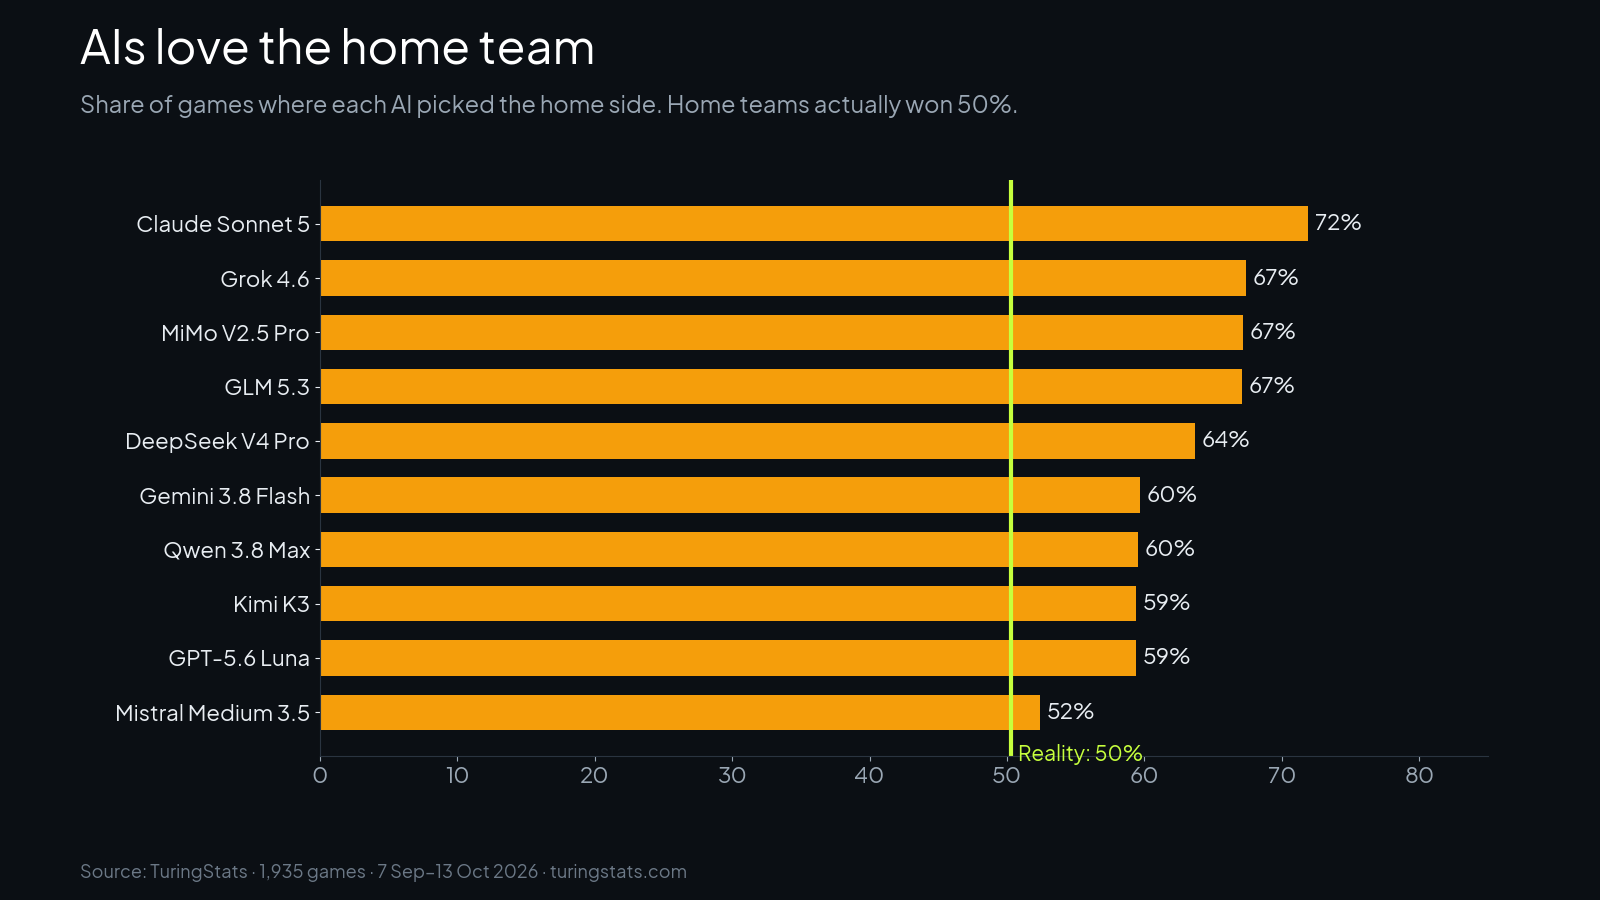
Home sides won 50% of these games. The models picked them between 52% (Mistral) and 72% (Claude) of the time.
The twist: Claude, the most home-heavy model, still finished first. It almost never predicts a draw (2% of its picks), and in soccer that turns out to be smart. About 22% of soccer matches ended level, but when any model called a draw it was right only 26% of the time. Calling draws is a losing game; the models that avoided them did better.
4. The real signal: when all 10 agree
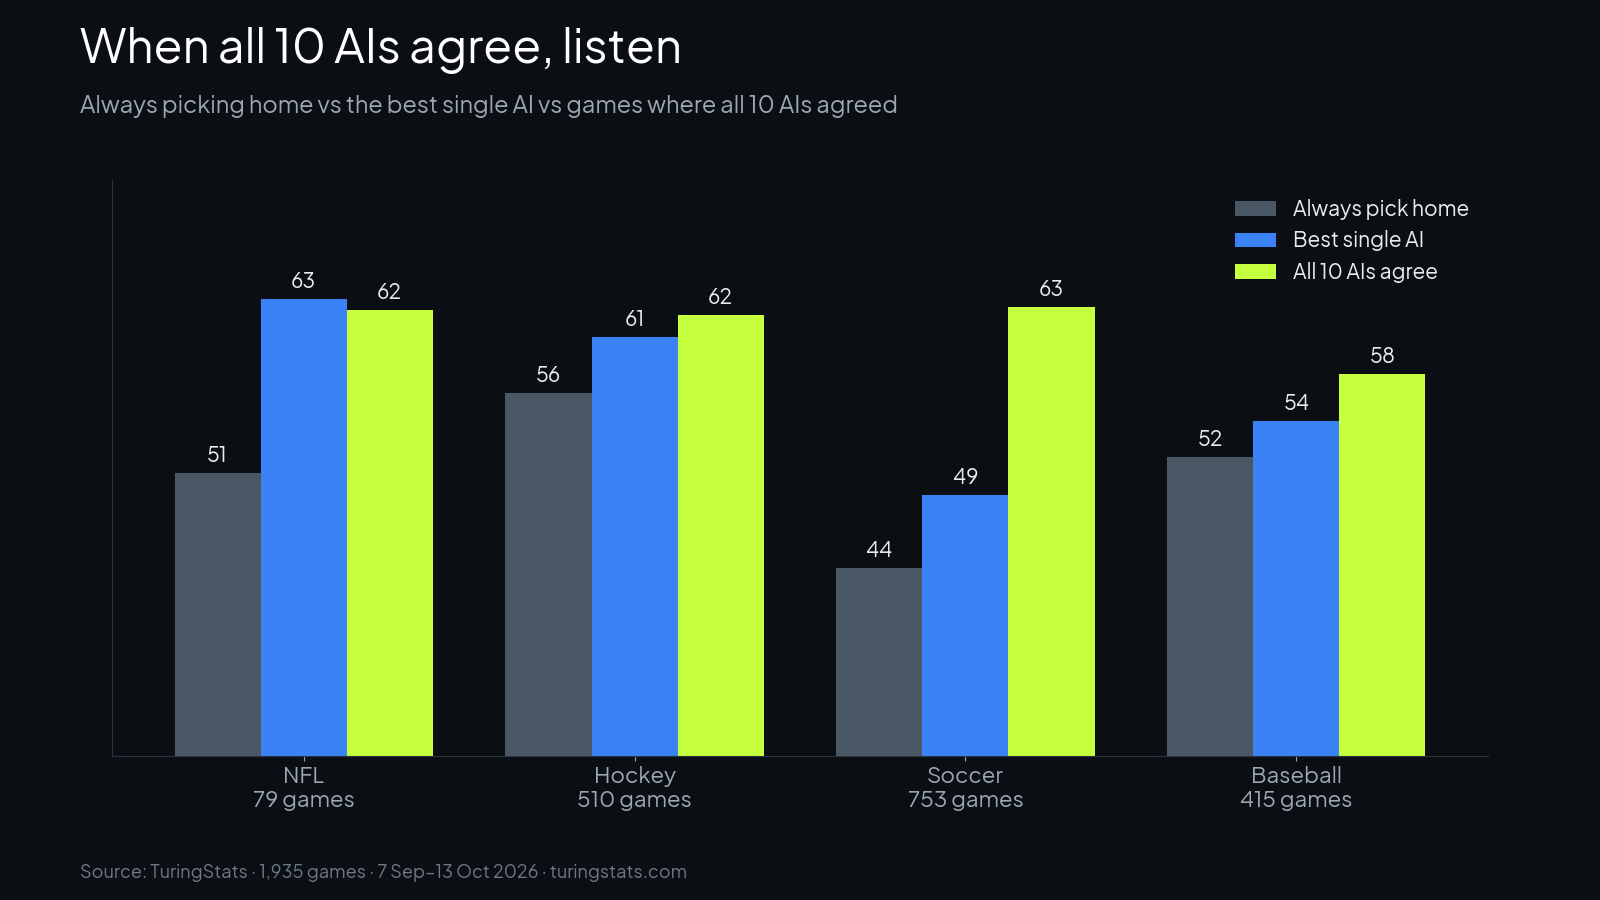
Single models top out around 54%. Agreement does better.
In soccer, picking the home team was right 44% of the time and the best single model reached 49%. In the 282 matches where all 10 models picked the same result, that pick was right 63% of the time. Hockey (62%) and baseball (58%) show the same pattern, smaller.
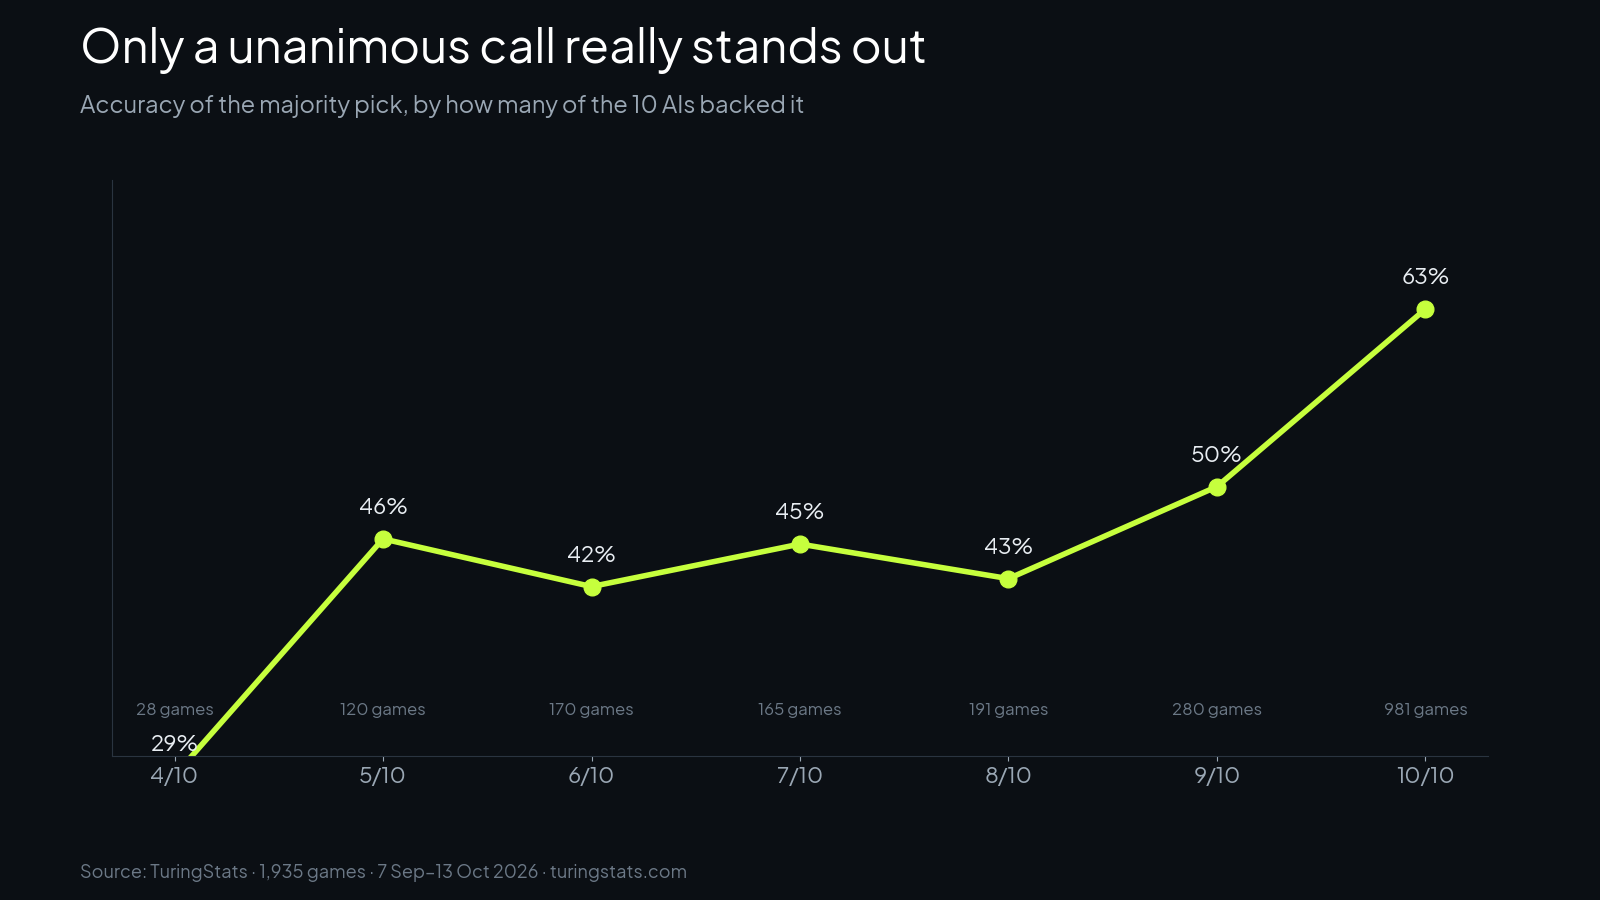
The effect is not gradual. A 7–3 or 8–2 split was right only 43–46% of the time, barely better than picking the home team. Only the unanimous call, 10 out of 10, stands clearly above the rest (63% across all sports, 981 games).
5. Baseball is close to unpredictable
In 415 MLB, NPB and KBO games, the best model managed 54% against 52% for "always pick home". If an app promises you strong baseball picks from AI, be sceptical.
Method
- Period: 7 Sep – 13 Oct 2026. This window starts the day the current 10-model line-up went live, so every model is compared on exactly the same 1,935 games.
- Games: soccer 753, hockey 510, baseball 415, NFL 79, plus volleyball, handball, NBA, basketball, rugby and AFL.
- Picks: each model returned home/draw/away, a score and a confidence (0–100) before kick-off, via OpenRouter, with the same match data and the same prompt. Betting odds were not in the prompt.
- Grading: a pick is correct if the predicted result matches the final result. Where a model was asked more than once for the same game, we used its latest pre-game pick.
- Limits: five weeks is short; the NFL sample (79 games) is small; we have not yet compared the models against bookmaker odds, which is the harder benchmark.
We will update this study monthly. Live, per-match picks from all 10 models are on turingstats.com and in the TuringStats app, where you can also ask all 10 the same question yourself.
Data and charts may be republished with credit and a link to TuringStats.
The AI prediction leaderboard updates after every result.
Ask all 10 AIs yourself: the TuringStats app is free on iPhone and Android.